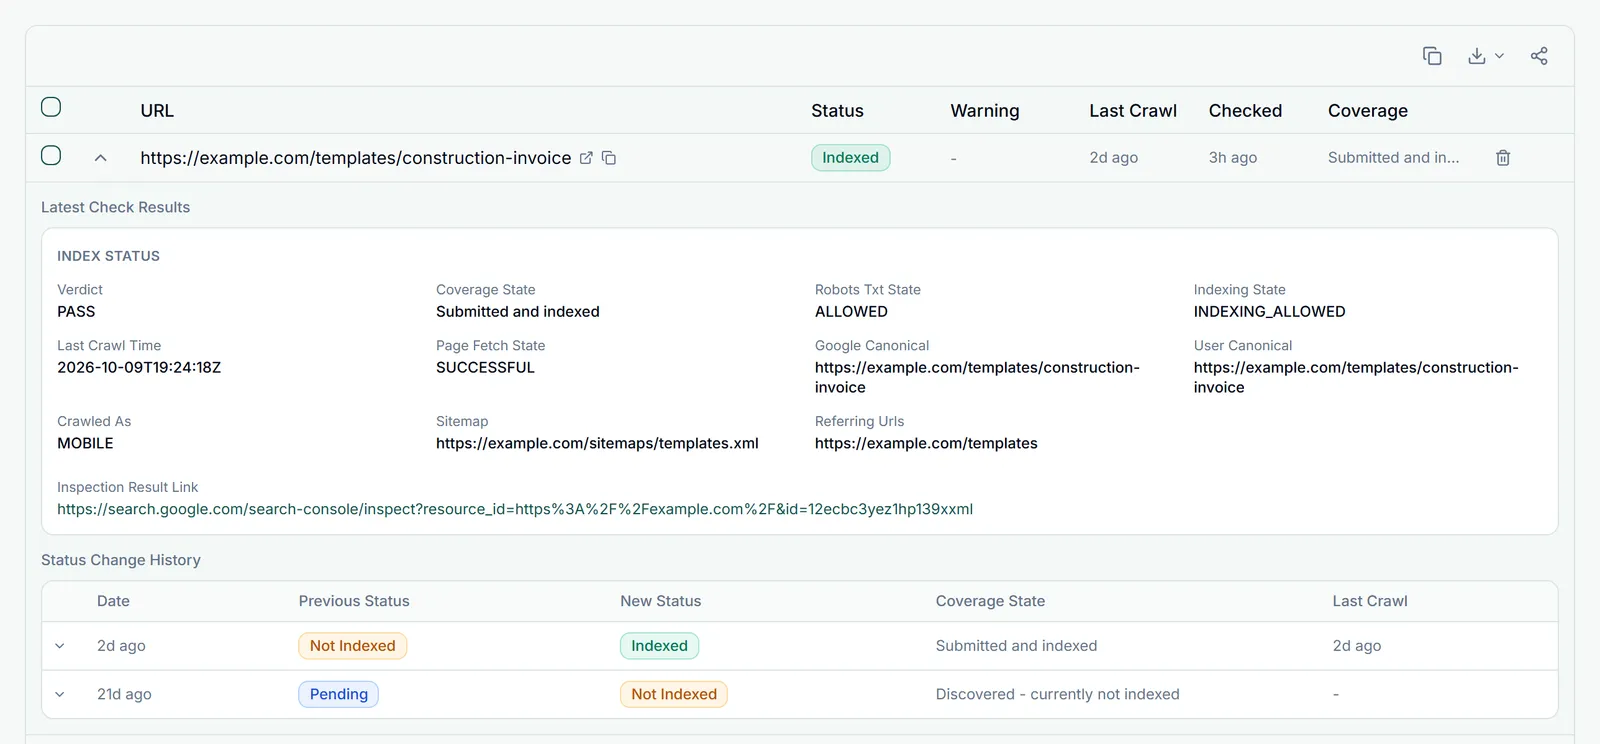
"Discovered - currently not indexed" is a status in the Pages report that means Google has found the URL (via your sitemap or links from other pages) but has not yet crawled it.
Why Does This Happen?
- Crawl budget constraints - Google allocates a limited crawl budget to each site. Lower-priority pages may sit in the queue for a long time before being crawled.
- New pages on lower-authority sites - Google tends to crawl new pages on high-authority sites faster.
- Crawl budget being wasted - If Google is spending crawl budget on faceted navigation, paginated URLs, or parameter URLs, important pages may not get crawled.
How to Fix It
- Build strong internal links to the discovered pages from high-traffic, already-indexed pages
- Improve content quality - Google is more likely to prioritize crawling pages it thinks will be useful
- Fix crawl budget waste - Block unimportant URL patterns via robots.txt
- Use Request Indexing for your most important pages
- Get external links pointing to the pages
Working through indexing issues on your site? Our technical indexing issues playbook gives you a full triage flow covering this status plus soft 404s, canonical conflicts, and robots.txt blocks.